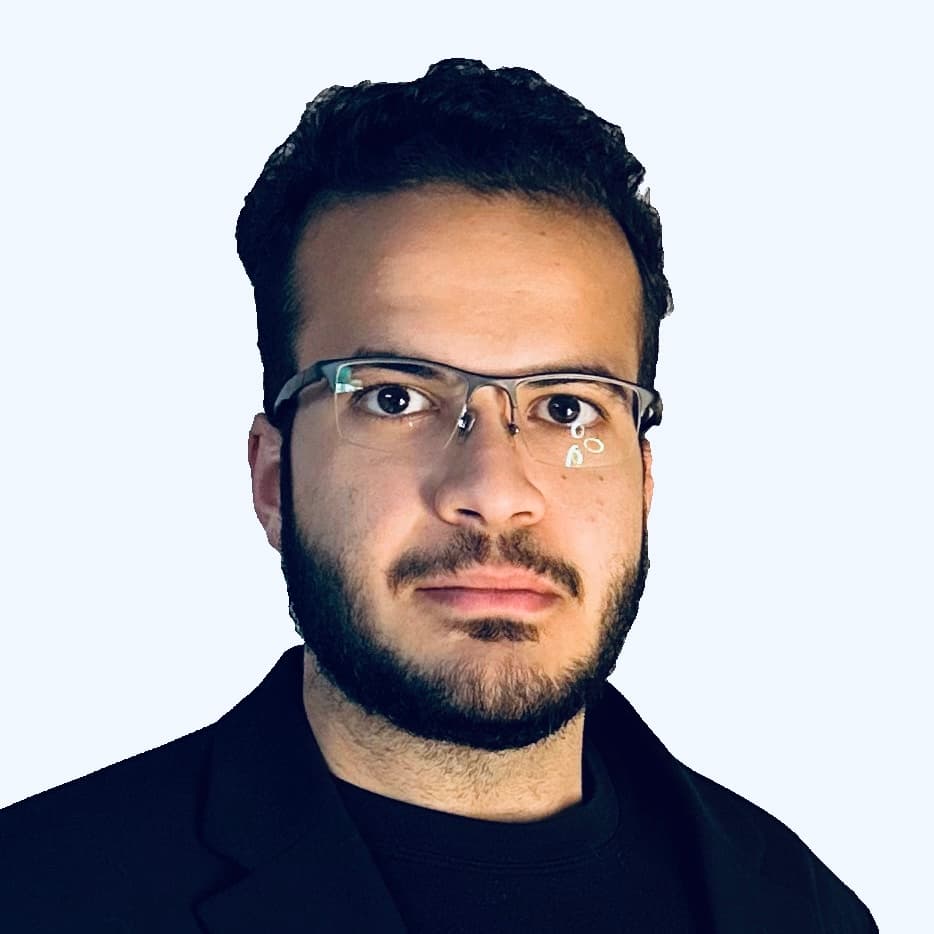
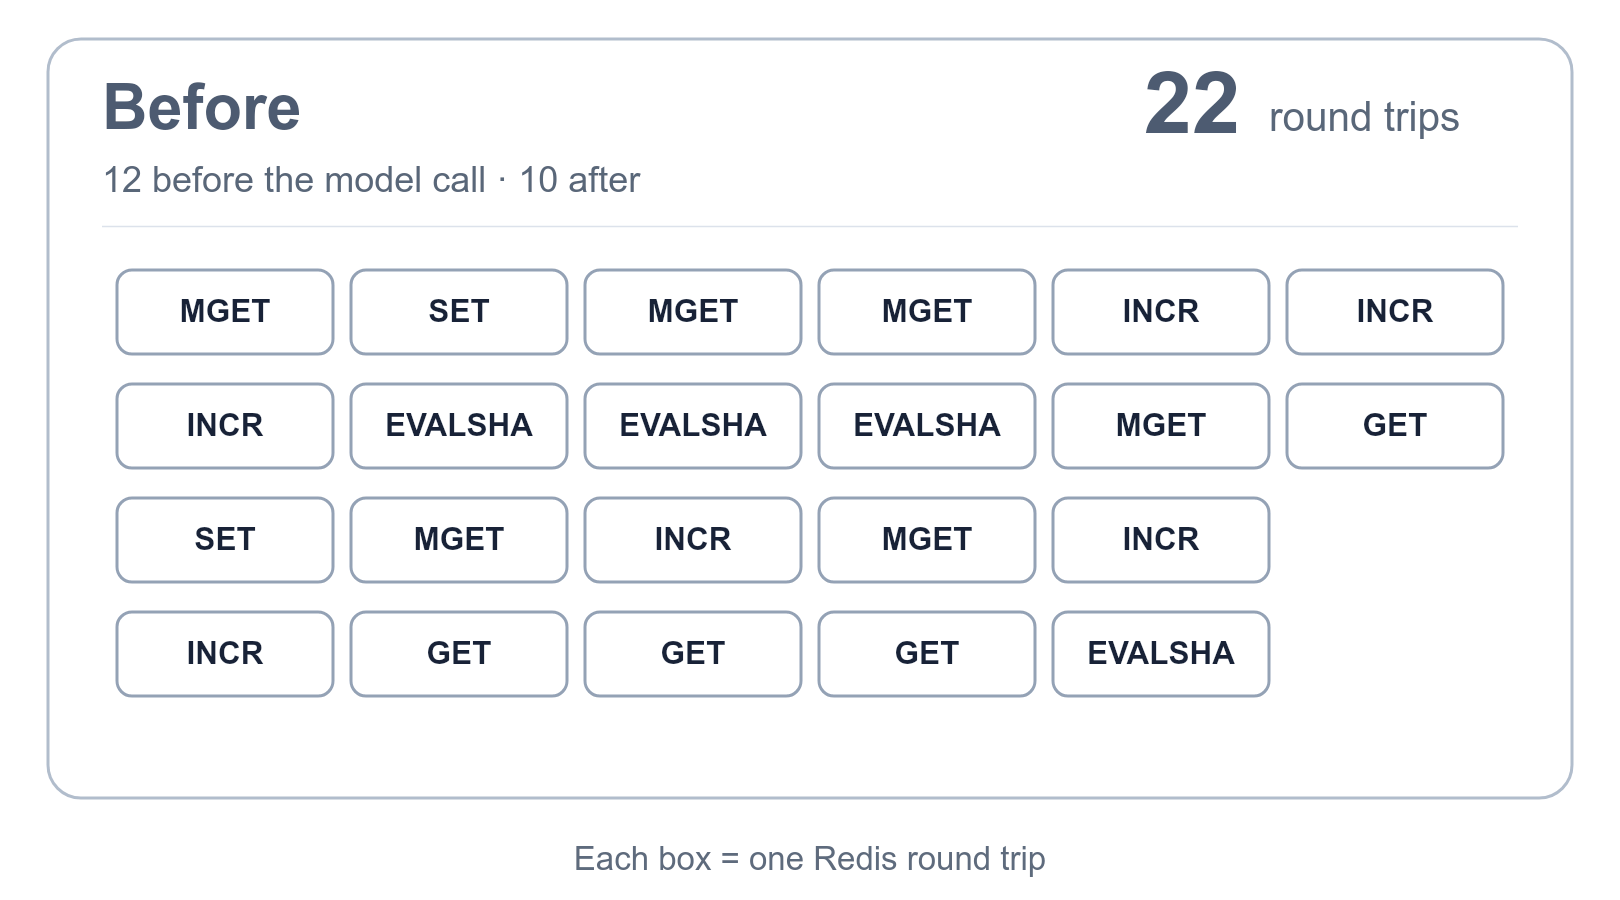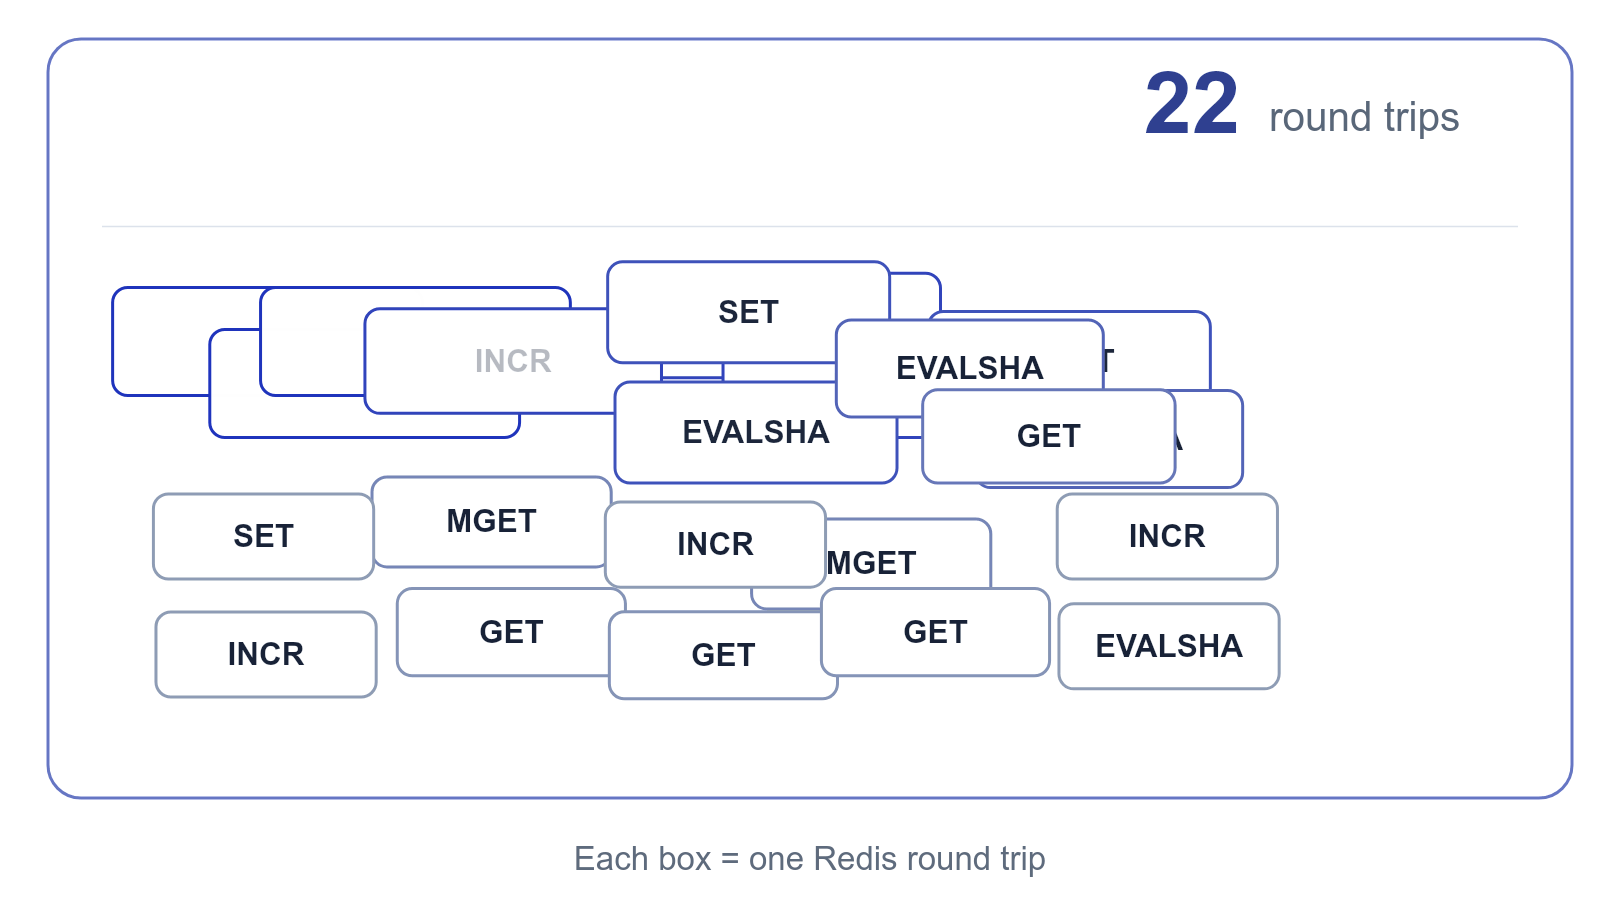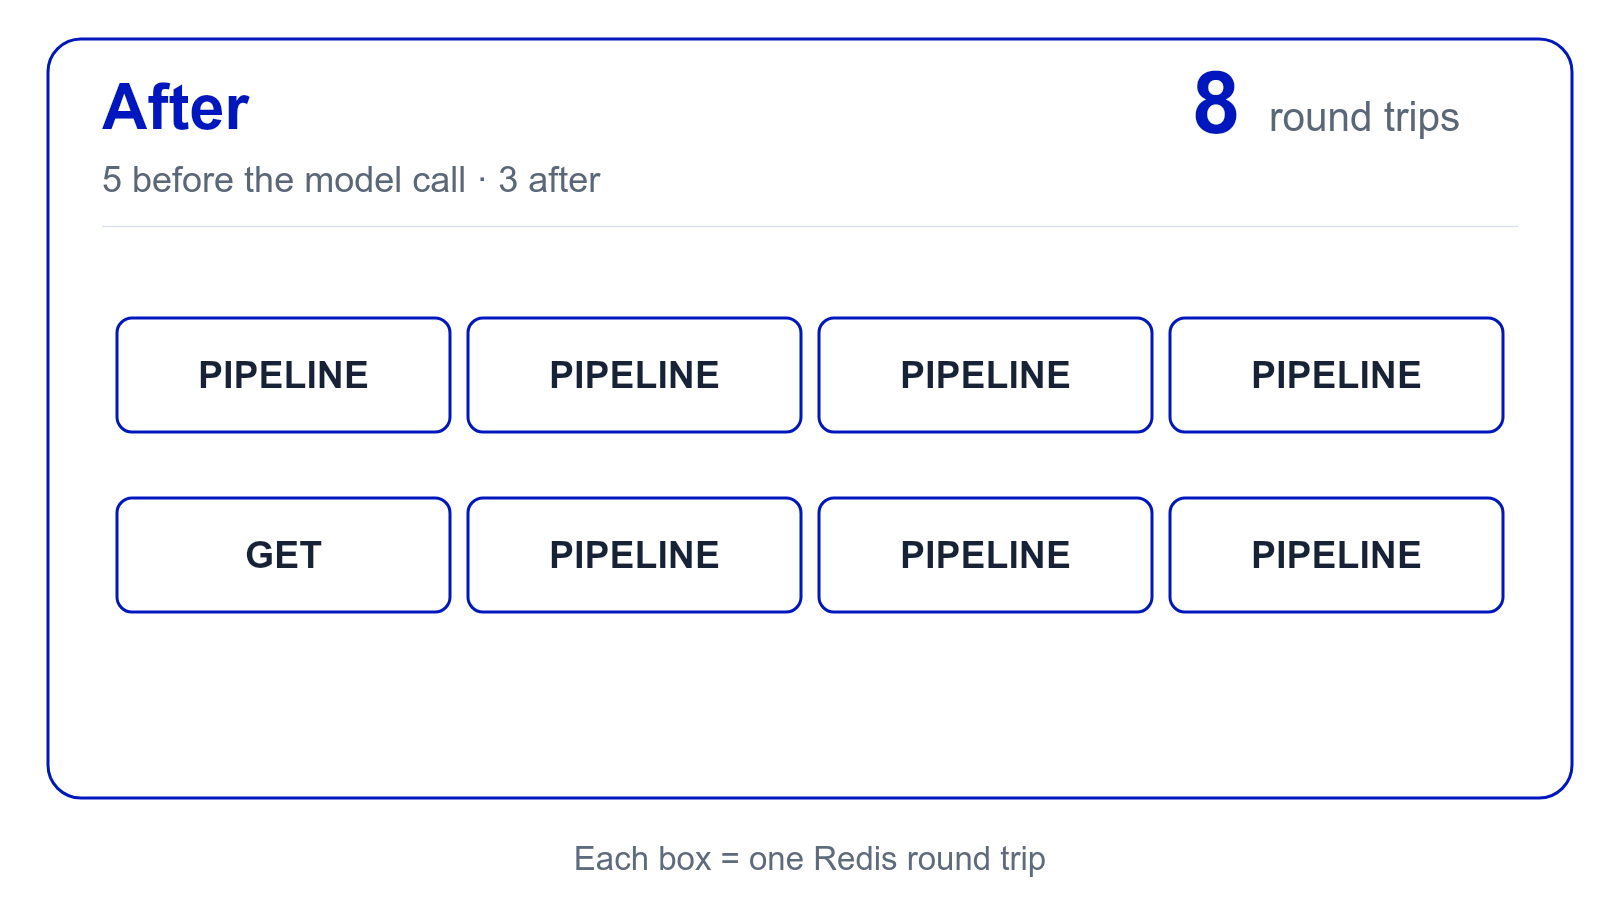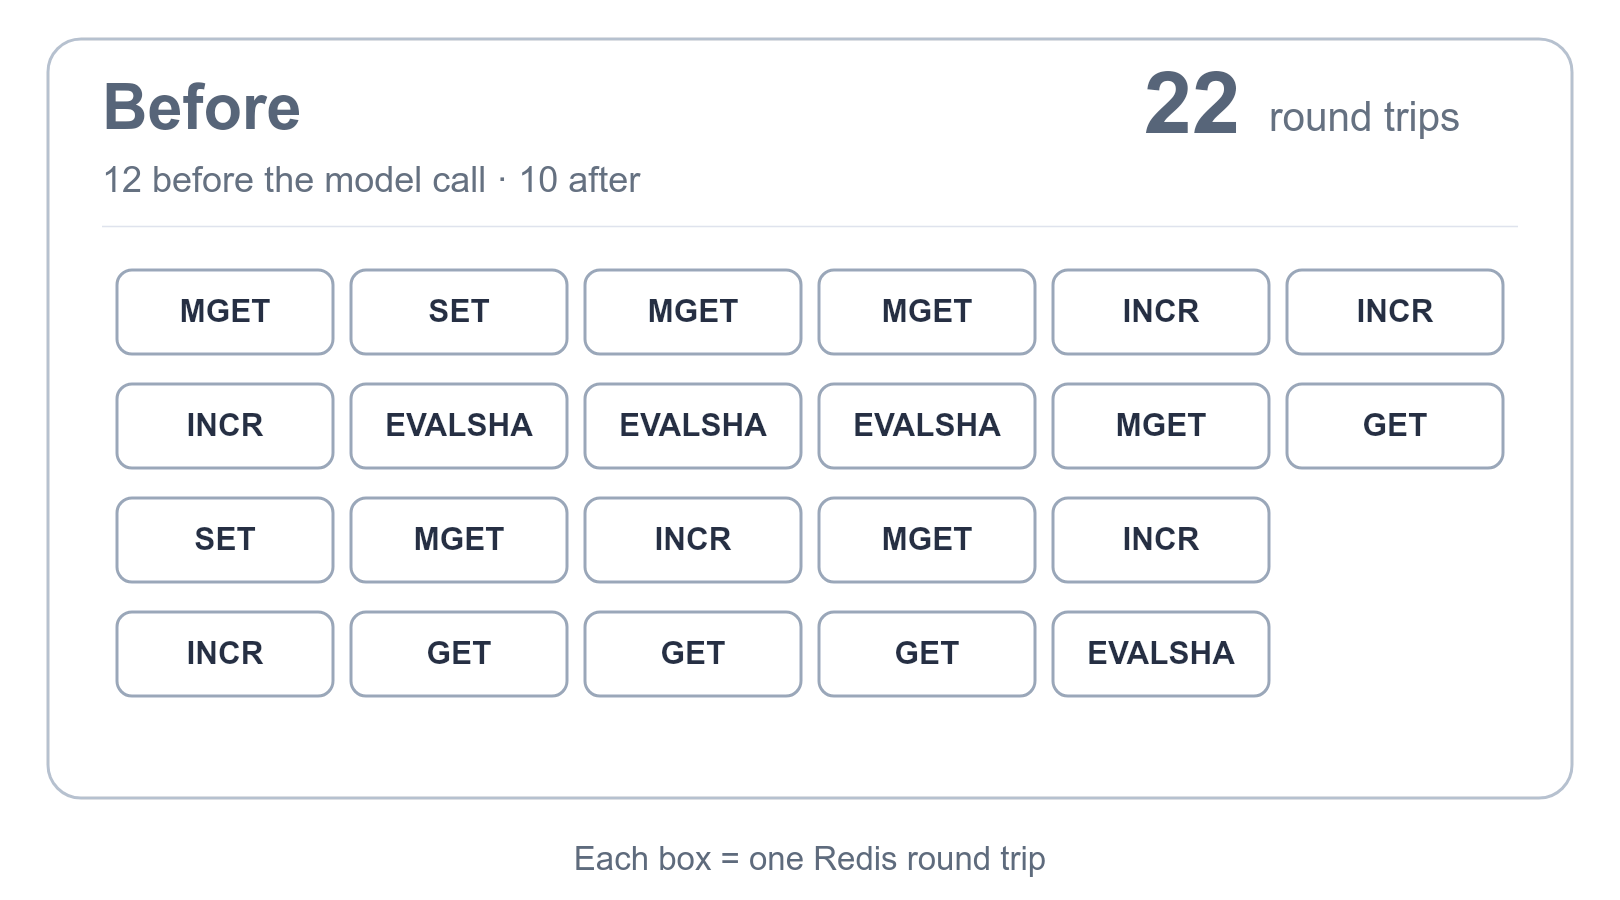
本週,我們將 LiteLLM proxy 上一個請求等待 Redis 的次數從 22 次降到 8 次。
一個來自具有預算之金鑰、位於具有預算與 TPM/RPM 限制之團隊、針對採用依使用量路由與 Redis 回應快取之模型群組的請求,原本會造成 22 次 Redis 往返:模型呼叫前 12 次、之後 10 次。相同的請求、相同的檢查與相同的寫入,現在只需 前 5 次、後 3 次。
Redis round trips per request
14 fewer Redis round trips per request| Redis round trips | Before | After |
|---|---|---|
| Before the model call | 12 | 5 |
| After the model call | 10 | 3 |
| Streaming request | 24 | 8 |
| Response-cache hit | 18 | 7 |
| Once-a-minute auth refresh | 46 | 16 |
為什麼會慢
proxy 在一次請求中與 Redis 溝通的部分有七個:auth、支出計數器、預算保留、速率限制器、router、回應快取,以及呼叫後的計帳。每一個都先讀取自己需要的資料、做出判斷、寫入,然後在下一個開始之前返回。光是速率限制器就連續執行了三個 Lua scripts。預算保留會重新讀取 auth 剛剛讀過的支出計數器,然後對每個實體各送出一次遞增。
在 22 次往返中,有 5 次承載了決策所依賴的資訊:身分資料列、支出計數器、速率限制 script、路由狀態,以及回應快取查詢。其餘 17 次是重複讀取已掌握的值、回寫,以及沒有人等待的計數器更新。Redis 從來不是瓶頸。成本在於等待答案,連續等 22 次,發生在每一次請求上。
- MGETteam, membership
- SETwrite back
- MGETspend counters
- MGETsame counters
- INCRreserve key
- INCRreserve team
- INCRreserve end user
- EVALSHARPM check
- EVALSHAkey TPM
- EVALSHAteam TPM
- MGETcooldowns, usage
- GETresponse cache
- model call
- SETresponse cache
- MGETspend counters
- INCRsettle reservation
- MGETsame counters
- INCRother counters
- INCRdeployment TPM
- GETuser spend
- GETtag spend
- GETtag spend
- EVALSHAtoken usage
- PIPELINEidentity MGET + spend MGET
- PIPELINEreserve key, team, end user
- PIPELINEidentity write back + routing MGET + RPM check
- PIPELINEkey TPM + team TPM
- GETresponse cache
- model call
- PIPELINEspend counters
- PIPELINEuser, tag spend
- PIPELINEcache SET + 8 counter INCRs + deployment TPM + token usage
我們做了什麼
現在每個請求都會擁有每個後端各一個 Redis 批次。 auth、支出檢查、速率限制器和 router 會在其中宣告它們要讀取的內容與 scripts,並取得一個 handle 回傳。任何人第一次 await 這個 handle 時,到目前為止已宣告的一切會一次以一個 pipeline 送出,而每個呼叫端都會讀取自己的回應。檢查本身沒有移動:預算拒絕仍然發生在預算程式碼中,速率限制拒絕仍然發生在速率限制器中,順序與之前相同。
Each subsystem reads, decides and writes before the next one starts
- AuthRead identity rows, write them back, read the spend counters
- BudgetsRead the same spend counters again, then reserve with three increments
- Rate limitsRun the RPM script, then the key TPM script, then the team TPM script
- Routing and cacheRead cooldowns and usage, pick a deployment, read the response cache
Declare, flush once, decide
- DeclareAuth, budgets, rate limits and routing queue their reads and scripts on the request batch and get a handle each
- FlushThe first await sends everything queued as one pipeline per Redis backend; every command gets its own reply
- DecideEach subsystem reads its reply and runs the same checks in the same order; a failed command fails only its owner
- SettleAfter the model call, writes collect in a post-call batch and leave in one pipeline once the callbacks finish
在模型回應後,沒有任何東西會等待那些寫入,因此它們會收集到一個呼叫後批次中:回應快取寫入、支出增量、部署使用量計數器,以及速率限制器的 token script。當成功或失敗回呼完成時,它們會一次以一個 pipeline 送出。如果沒有任何回呼關閉它,則一個一秒的期限會強制 flush 該批次,而 shutdown 會排空所有仍在等待的內容,因此 pod 重新啟動不會遺失計帳。
pipeline 中的每個命令都會取得自己的回應。尚未載入的 Lua script 只會讓其擁有者失敗,並像之前一樣退回到直接呼叫。整個 pipeline 失敗時,對每個擁有者來說都像是 Redis 無法連線,這正是他們已經在處理的情況。Redis Cluster client 仍會進行直接呼叫,因為 cluster pipeline 會依節點分散。觸及兩個 Redis 後端的請求,會對每個後端各使用一個 pipeline;而 proxy 與 router 的快取若指向同一台伺服器,就會共用一個 pipeline。
每次請求的 Redis 往返次數:22 → 8
相同的測試框架以相同方式執行 proxy 管理的每一種 endpoint 形狀,包含與不包含 streaming、包含依使用量與簡單隨機洗牌路由,以及有回應快取命中的情況。/v1/responses 每一側都多保留一次往返,因為其原生 handler 仍從 worker thread 進行兩次同步快取呼叫。
| Request | Before | After |
|---|---|---|
/v1/chat/completions | 22 | 8 |
/v1/chat/completionsstreaming | 24 | 8 |
/v1/chat/completionssimple-shuffle routing | 22 | 8 |
/v1/messages | 21 | 8 |
/v1/responses | 26 | 9 |
/v1/chat/completionsresponse-cache hit | 18 | 7 |
auth 重新整理請求:46 → 16 次 Redis 往返
auth 會將其管理物件、key、end user、team 與 model-access registry 保留在記憶體中 60 秒。在它們過期後的第一個請求中,proxy 會逐一從 Redis,然後從 Postgres 重新整理每一個物件:在路由開始前有 16 次連續的 Redis 往返,end user、key 與 registry 各讀取兩次,而 team alias 則在 event loop 上以同步呼叫刪除。對於每個活躍 key,每分鐘一次,這個請求的成本從 22 次往返變成 46 次。
現在,相同的請求會在 request pipeline 上透過一次 MGET 讀取記憶體中缺少的內容、讀取 team,並將回寫與 alias 刪除作為其後的一個 pipeline 送出。重新整理現在是 3 次往返,而整體請求則從 46 次降到 16 次往返(chat),以及從 40 次降到 14 次(/v1/messages)。
我們如何測量
我們在同一個本機 proxy 上測量了兩個版本,從這項工作之前的 commit(27c110cb)到包含全部五項變更的 main(13d004fc):Redis 6.0 與 Postgres 14、mock deployments(因此計數不依賴任何提供者),以及一個會記錄每次 Redis 呼叫與每次 pipeline flush 及其呼叫者的 tracer。一次 pipeline 或一次 Lua script 算作一次往返。每個樣本前 12 秒都會先送出一個 warm-up 請求,且測試框架每三個樣本就會閒置 65 秒,因此 60 秒的快取到期永遠不會落在樣本內。對於重新整理案例,測試框架先送出一個 warm-up 請求,等待 65 秒,然後追蹤下一個請求。兩邊的所有請求都回傳 HTTP 200。
請參閱變更:路由讀取、支出計數器、呼叫前 pipeline、呼叫後 pipeline 以及 auth 重新整理。