使用 LiteLLM 對多個 LLM 提供者進行可靠性測試
- 品質測試
- 負載測試
- 持續時間測試
uv add litellm python-dotenv
import litellm
from litellm.utils import load_test_model
import time
from dotenv import load_dotenv
load_dotenv()
品質測試端點
在多個 LLM 提供者之間測試相同的提示
在這個範例中,我們來問一些關於 Paul Graham 的問題
models = ["gpt-5.6-luna", "gpt-5.6-terra", "claude-sonnet-5", "replicate/llama-2-70b-chat:58d078176e02c219e11eb4da5a02a7830a283b14cf8f94537af893ccff5ee781"]
context = """Paul Graham (/ɡræm/; born 1964)[3] is an English computer scientist, essayist, entrepreneur, venture capitalist, and author. He is best known for his work on the programming language Lisp, his former startup Viaweb (later renamed Yahoo! Store), cofounding the influential startup accelerator and seed capital firm Y Combinator, his essays, and Hacker News. He is the author of several computer programming books, including: On Lisp,[4] ANSI Common Lisp,[5] and Hackers & Painters.[6] Technology journalist Steven Levy has described Graham as a "hacker philosopher".[7] Graham was born in England, where he and his family maintain permanent residence. However he is also a citizen of the United States, where he was educated, lived, and worked until 2016."""
prompts = ["Who is Paul Graham?", "What is Paul Graham known for?" , "Is paul graham a writer?" , "Where does Paul Graham live?", "What has Paul Graham done?"]
messages =  [[{"role": "user", "content": context + "\n" + prompt}] for prompt in prompts] # pass in a list of messages we want to test
result = [litellm.batch_completion_models_all_responses(models=models, messages=message) for message in messages]
batch_completion_models_all_responses 會將一則對話平行送到每個模型,並回傳成功的回應,因此請對提示逐一迴圈處理。拋出例外的模型會從回傳清單中移除,而不會以錯誤形式顯示
負載測試端點
跨多個提供者執行 100+ 個同時請求,以觀察它們何時失敗,以及對延遲的影響。load_test_model 只接受一個 model,因此請針對每個提供者呼叫一次。
models=["gpt-5.6-luna", "replicate/llama-2-70b-chat:58d078176e02c219e11eb4da5a02a7830a283b14cf8f94537af893ccff5ee781", "claude-sonnet-5"]
context = """Paul Graham (/ɡræm/; born 1964)[3] is an English computer scientist, essayist, entrepreneur, venture capitalist, and author. He is best known for his work on the programming language Lisp, his former startup Viaweb (later renamed Yahoo! Store), cofounding the influential startup accelerator and seed capital firm Y Combinator, his essays, and Hacker News. He is the author of several computer programming books, including: On Lisp,[4] ANSI Common Lisp,[5] and Hackers & Painters.[6] Technology journalist Steven Levy has described Graham as a "hacker philosopher".[7] Graham was born in England, where he and his family maintain permanent residence. However he is also a citizen of the United States, where he was educated, lived, and worked until 2016."""
prompt = "Where does Paul Graham live?"
final_prompt = context + prompt
num_calls = 5
result = {model: load_test_model(model=model, prompt=final_prompt, num_calls=num_calls) for model in models}
load_test_model 會同時送出 num_calls 個請求,但它回傳的 calls_made 欄位無論 num_calls 為何,永遠都是 100,因此在計算平均值時請除以您自己的 num_calls
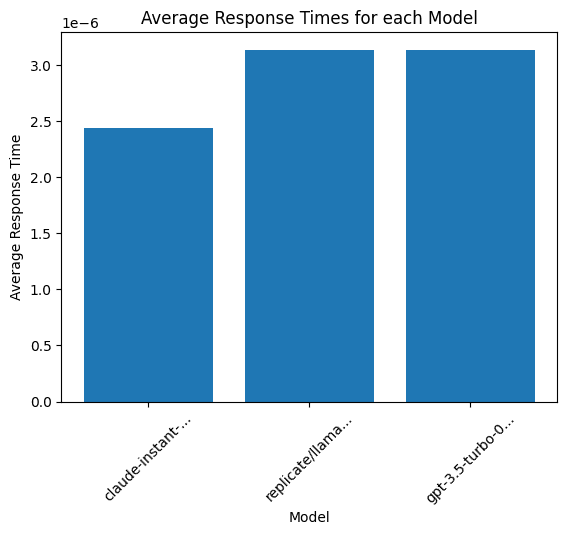
視覺化資料
import matplotlib.pyplot as plt

## calculate avg response time
avg_response_time = {}
for model, load_result in result.items():
    avg_response_time[model] = load_result["total_response_time"] / num_calls

models = list(avg_response_time.keys())
response_times = list(avg_response_time.values())

plt.bar(models, response_times)
plt.xlabel('Model', fontsize=10)
plt.ylabel('Average Response Time')
plt.title('Average Response Times for each Model')

plt.xticks(models, [model[:15]+'...' if len(model) > 15 else model for model in models], rotation=45)
plt.show()
持續時間測試端點
執行 2 分鐘的負載測試。每 15 秒對端點發送 100+ 個請求。load_test_model 沒有間隔或持續時間選項,因此請自行迴圈呼叫。
models=["gpt-5.6-luna", "replicate/llama-2-70b-chat:58d078176e02c219e11eb4da5a02a7830a283b14cf8f94537af893ccff5ee781", "claude-sonnet-5"]
context = """Paul Graham (/ɡræm/; born 1964)[3] is an English computer scientist, essayist, entrepreneur, venture capitalist, and author. He is best known for his work on the programming language Lisp, his former startup Viaweb (later renamed Yahoo! Store), cofounding the influential startup accelerator and seed capital firm Y Combinator, his essays, and Hacker News. He is the author of several computer programming books, including: On Lisp,[4] ANSI Common Lisp,[5] and Hackers & Painters.[6] Technology journalist Steven Levy has described Graham as a "hacker philosopher".[7] Graham was born in England, where he and his family maintain permanent residence. However he is also a citizen of the United States, where he was educated, lived, and worked until 2016."""
prompt = "Where does Paul Graham live?"
final_prompt = context + prompt
interval = 15
duration = 120
result = []
num_calls = 100
end_time = time.time() + duration
while time.time() < end_time:
    result.append({model: load_test_model(model=model, prompt=final_prompt, num_calls=num_calls) for model in models})
    time.sleep(interval)
import matplotlib.pyplot as plt

## calculate avg response time
model_dict = {model: {"response_time": []} for model in models}
for iteration in result:
  for model, load_result in iteration.items():
    model_dict[model]["response_time"].append(load_result["total_response_time"] / num_calls)

avg_response_time = {}
for model, data in model_dict.items():
    avg_response_time[model] = sum(data["response_time"]) / len(data["response_time"])

models = list(avg_response_time.keys())
response_times = list(avg_response_time.values())

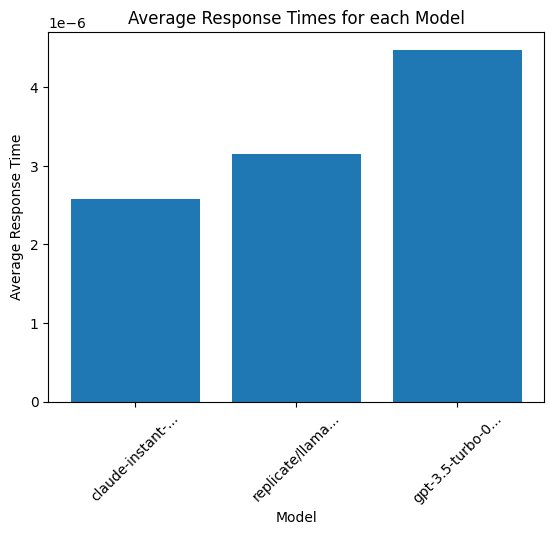
plt.bar(models, response_times)
plt.xlabel('Model', fontsize=10)
plt.ylabel('Average Response Time')
plt.title('Average Response Times for each Model')

plt.xticks(models, [model[:15]+'...' if len(model) > 15 else model for model in models], rotation=45)
plt.show()